
The situation
Agents pay for every byte they read, then pay again on every turn, because models are stateless and the context is resent each call. Scattered data makes it worse: the agent lists several silos, opens the wrong files, and drags them through the whole conversation.What OneBucket changes
Ask first, fetch once. Metadata answers where an object is and how big it is; only the matching object enters context. Large files and heavy work stay outside the model and only the result comes back. Hot data is pre-positioned for the next turn.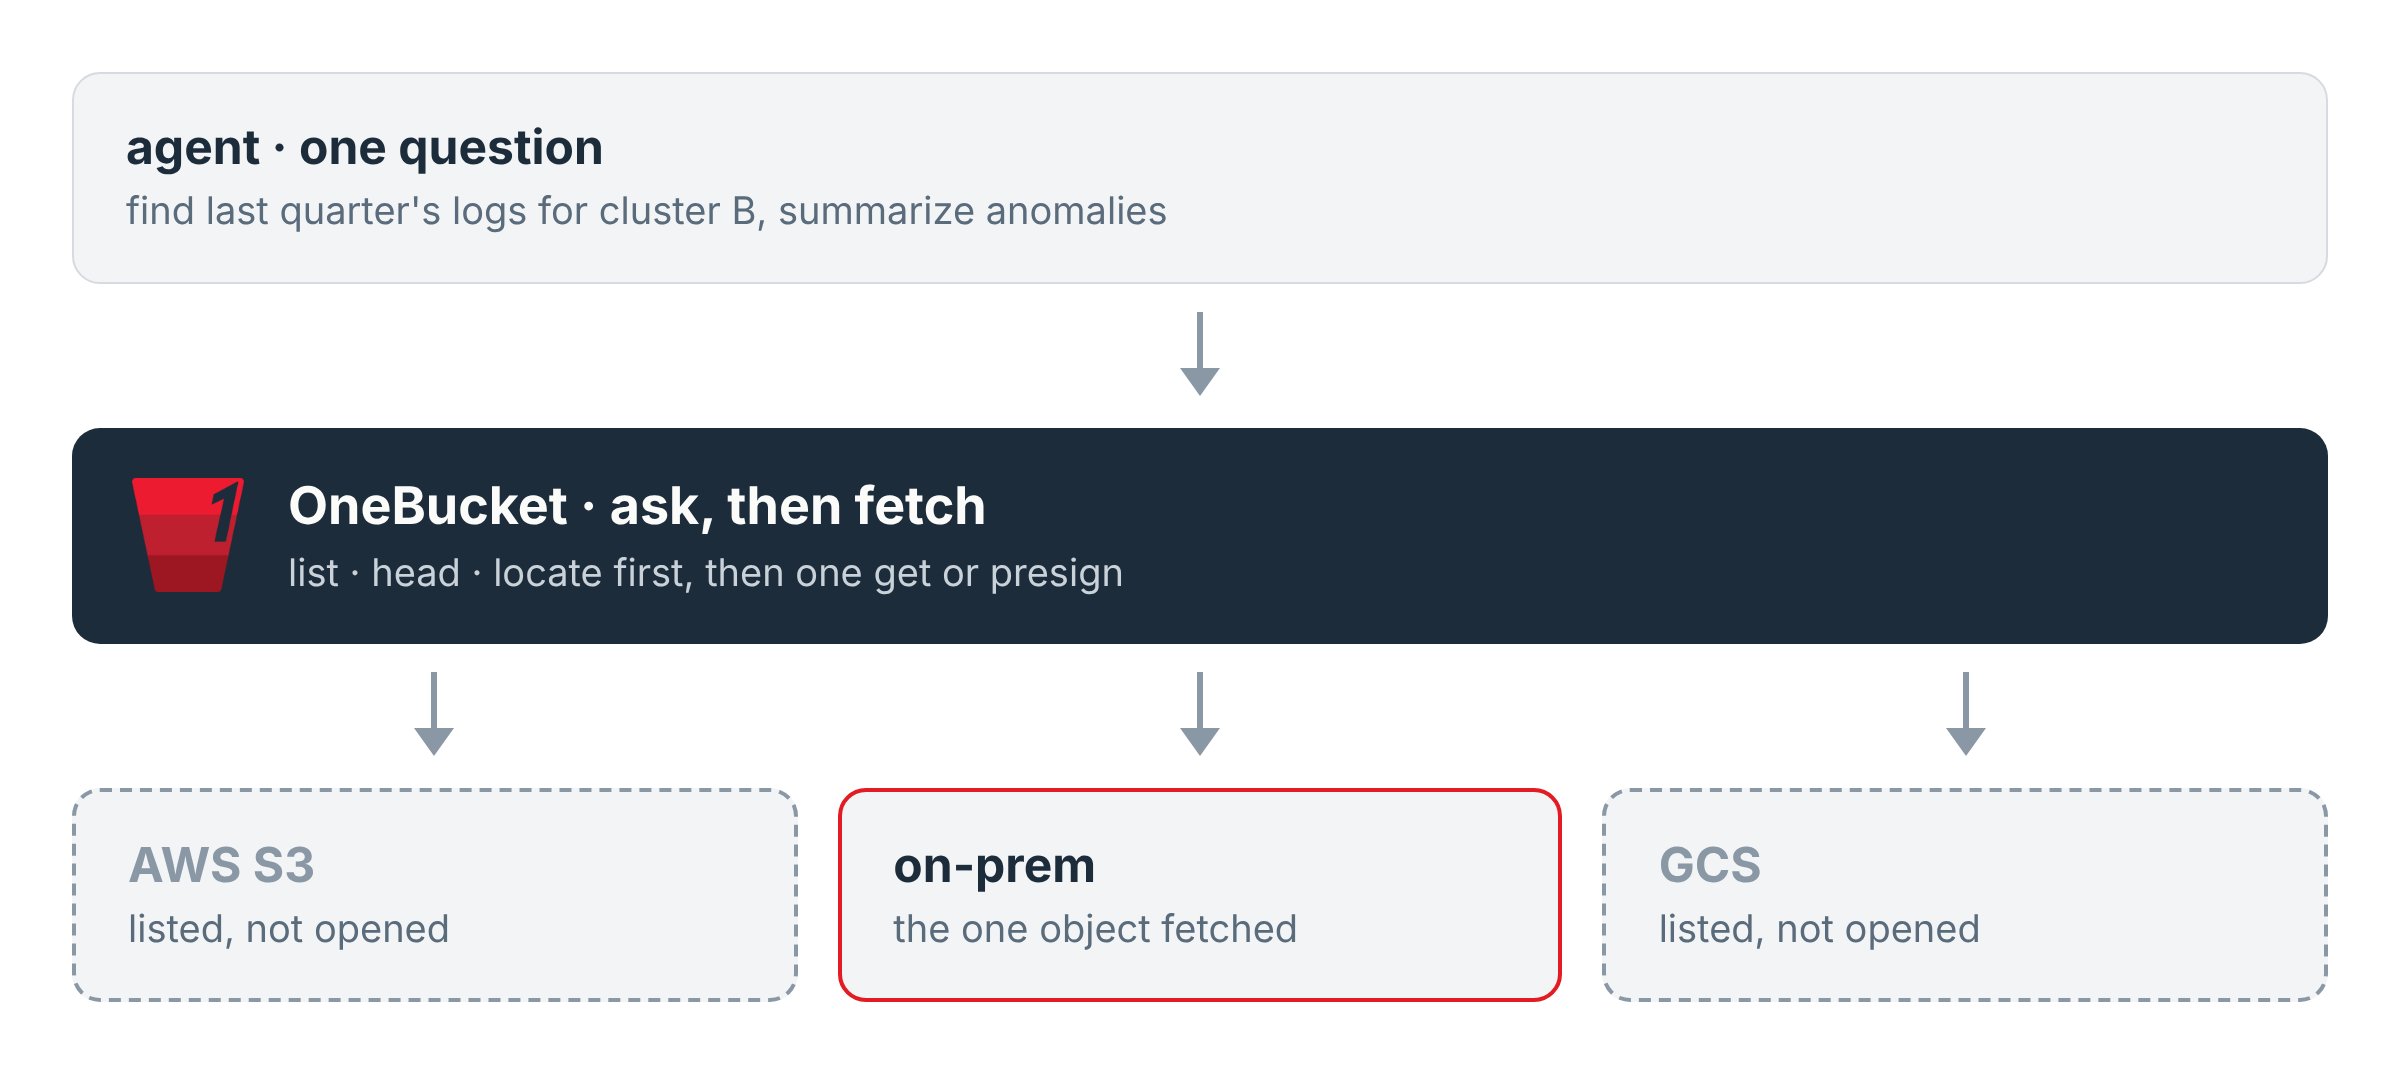
The pattern
- One lookup for discovery. One namespace and one MCP server, so finding data is a single
listwith a prefix and paging, not a search across silos. - Metadata before content.
headreturns size, type and timestamps without the body.locatereturns where the object lives. - Fetch only the match. One
getfor the object that answers the question. Inline reads are capped; above the cap,presignreturns a URL so code can process the file outside the context window and hand back only the result. - Pre-position for the next turn.
prefetchmoves hot data next to where the next step runs.
Related
- Claude connector:
list,head,locate,presign,prefetch - Agents reach data through MCP