
The situation
Training or inference runs in a GPU cloud, while the data sits in AWS, in another cloud and on-premises. Jobs wait on remote reads, GPUs sit idle, and every epoch pays egress again. Moving the data wholesale is not an option.What OneBucket changes
A cache-mode peer bucket sits in the GPU cloud, under the same namespace. Prefetch warms it before a job, by policy or on request. Reads are served locally and stay in sync with the source. The source remains the system of record and nothing is rearchitected.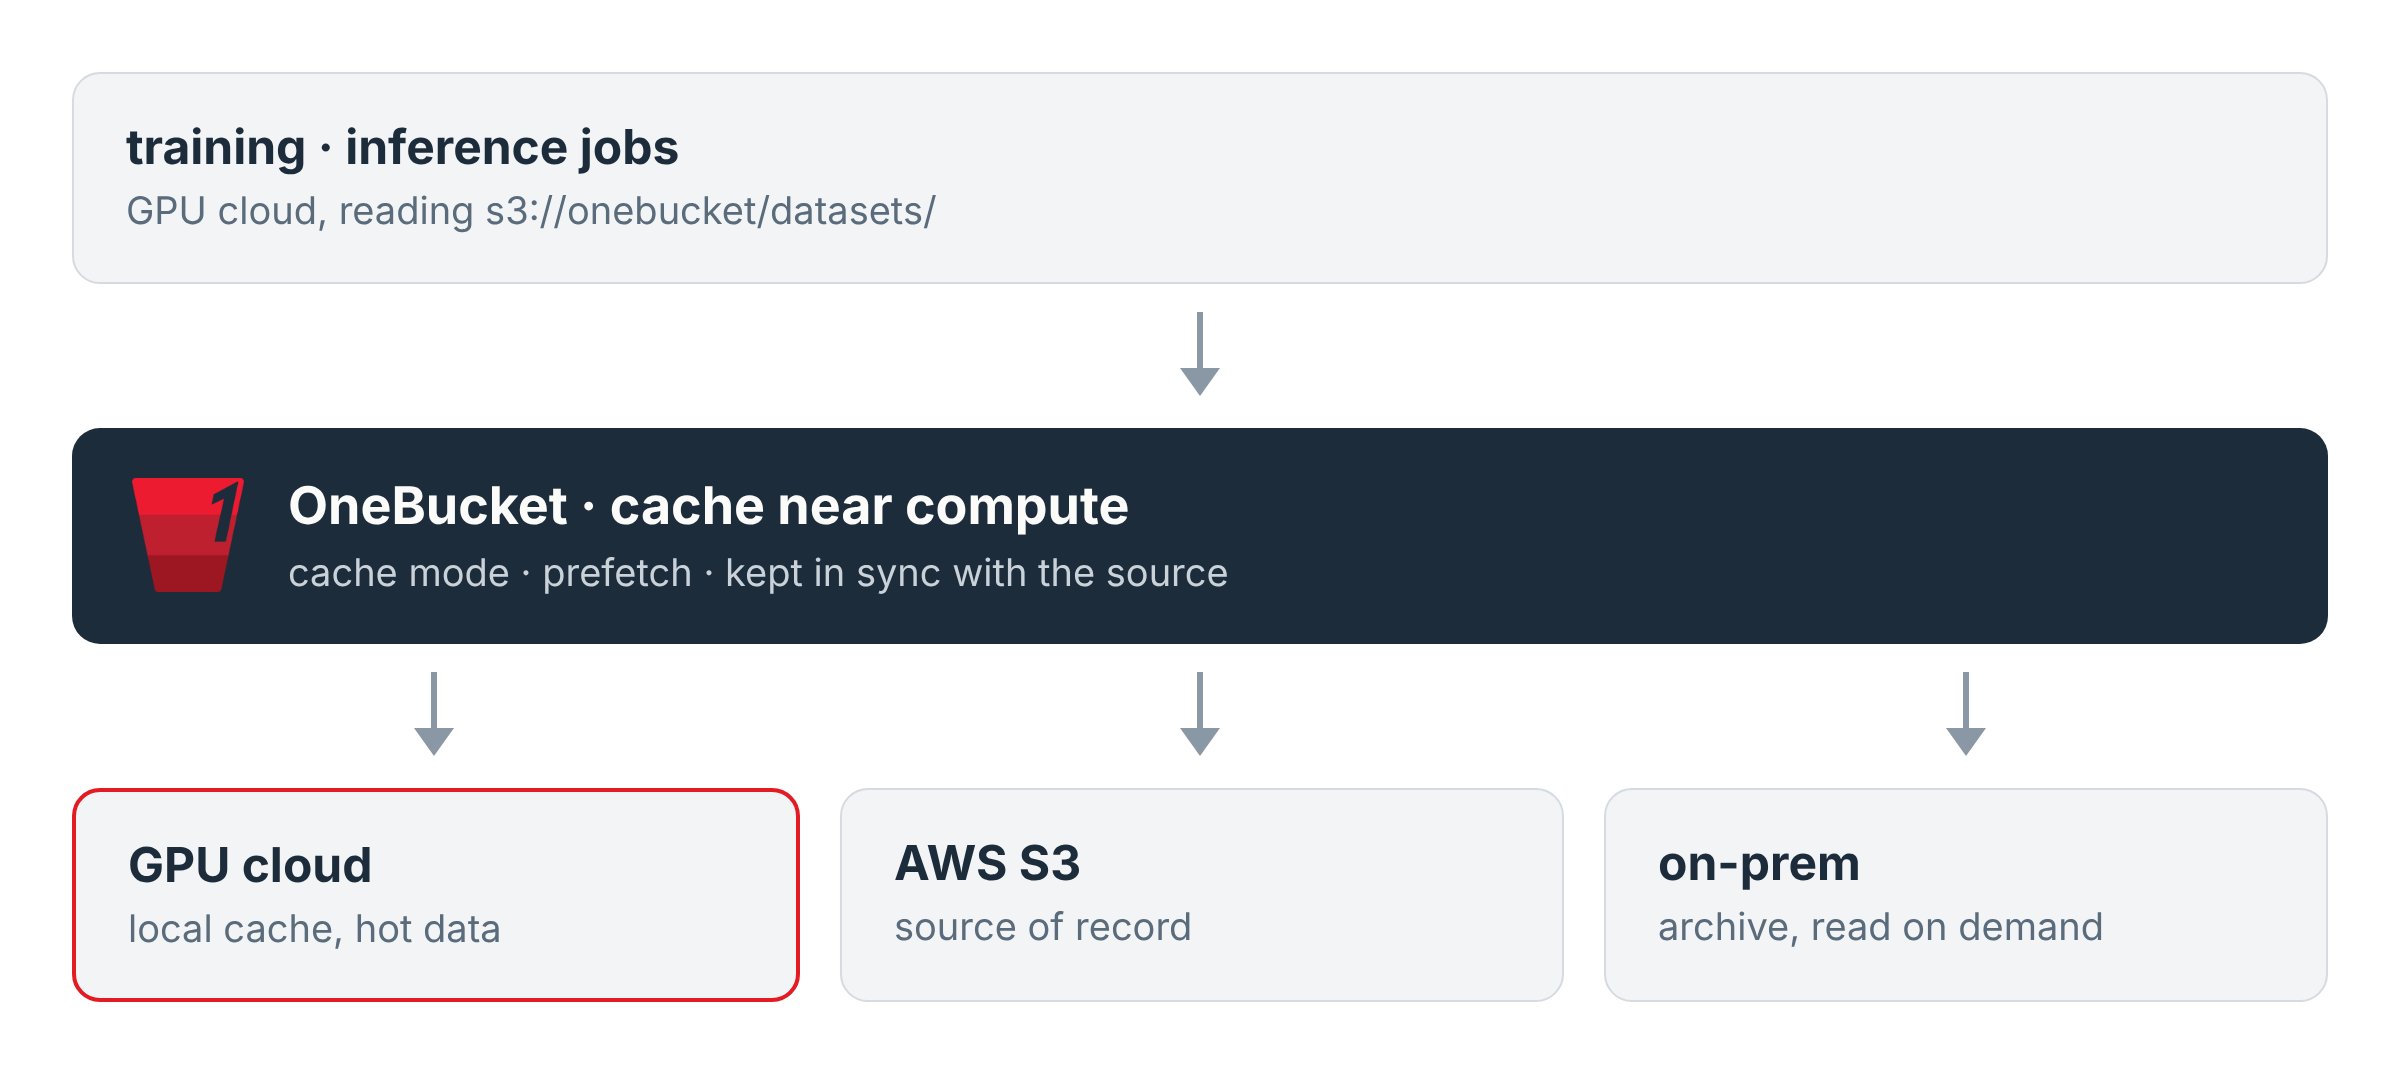
How it works
- Cache-mode peer. Add a peer bucket in
cachemode located at the GPU provider. It holds a copy of what has been read or prefetched; the source stays authoritative. - Prefetch. Warm the cache ahead of a run with the
prefetchtool over MCP, or by policy. Warming is asynchronous: a destination may not be readable the instant prefetch is queued. - Local reads. Jobs read the same path they always did; the read is served from the cache. Data crosses the cloud boundary once rather than once per job.
Related
- Set up your OneBucket: cache mode
- Claude connector:
prefetch,locate - Placement by policy