
The situation
Tabular data lands as Parquet in different places: one business unit on AWS, another on GCS, history on-premises. Every analysis starts by exporting, copying and stitching sources together.What OneBucket changes
All of it appears under one bucket and one prefix layout. Any S3-reading engine reads the files together in one query. Nothing is copied first. The join across stores disappears because there is nothing to stitch.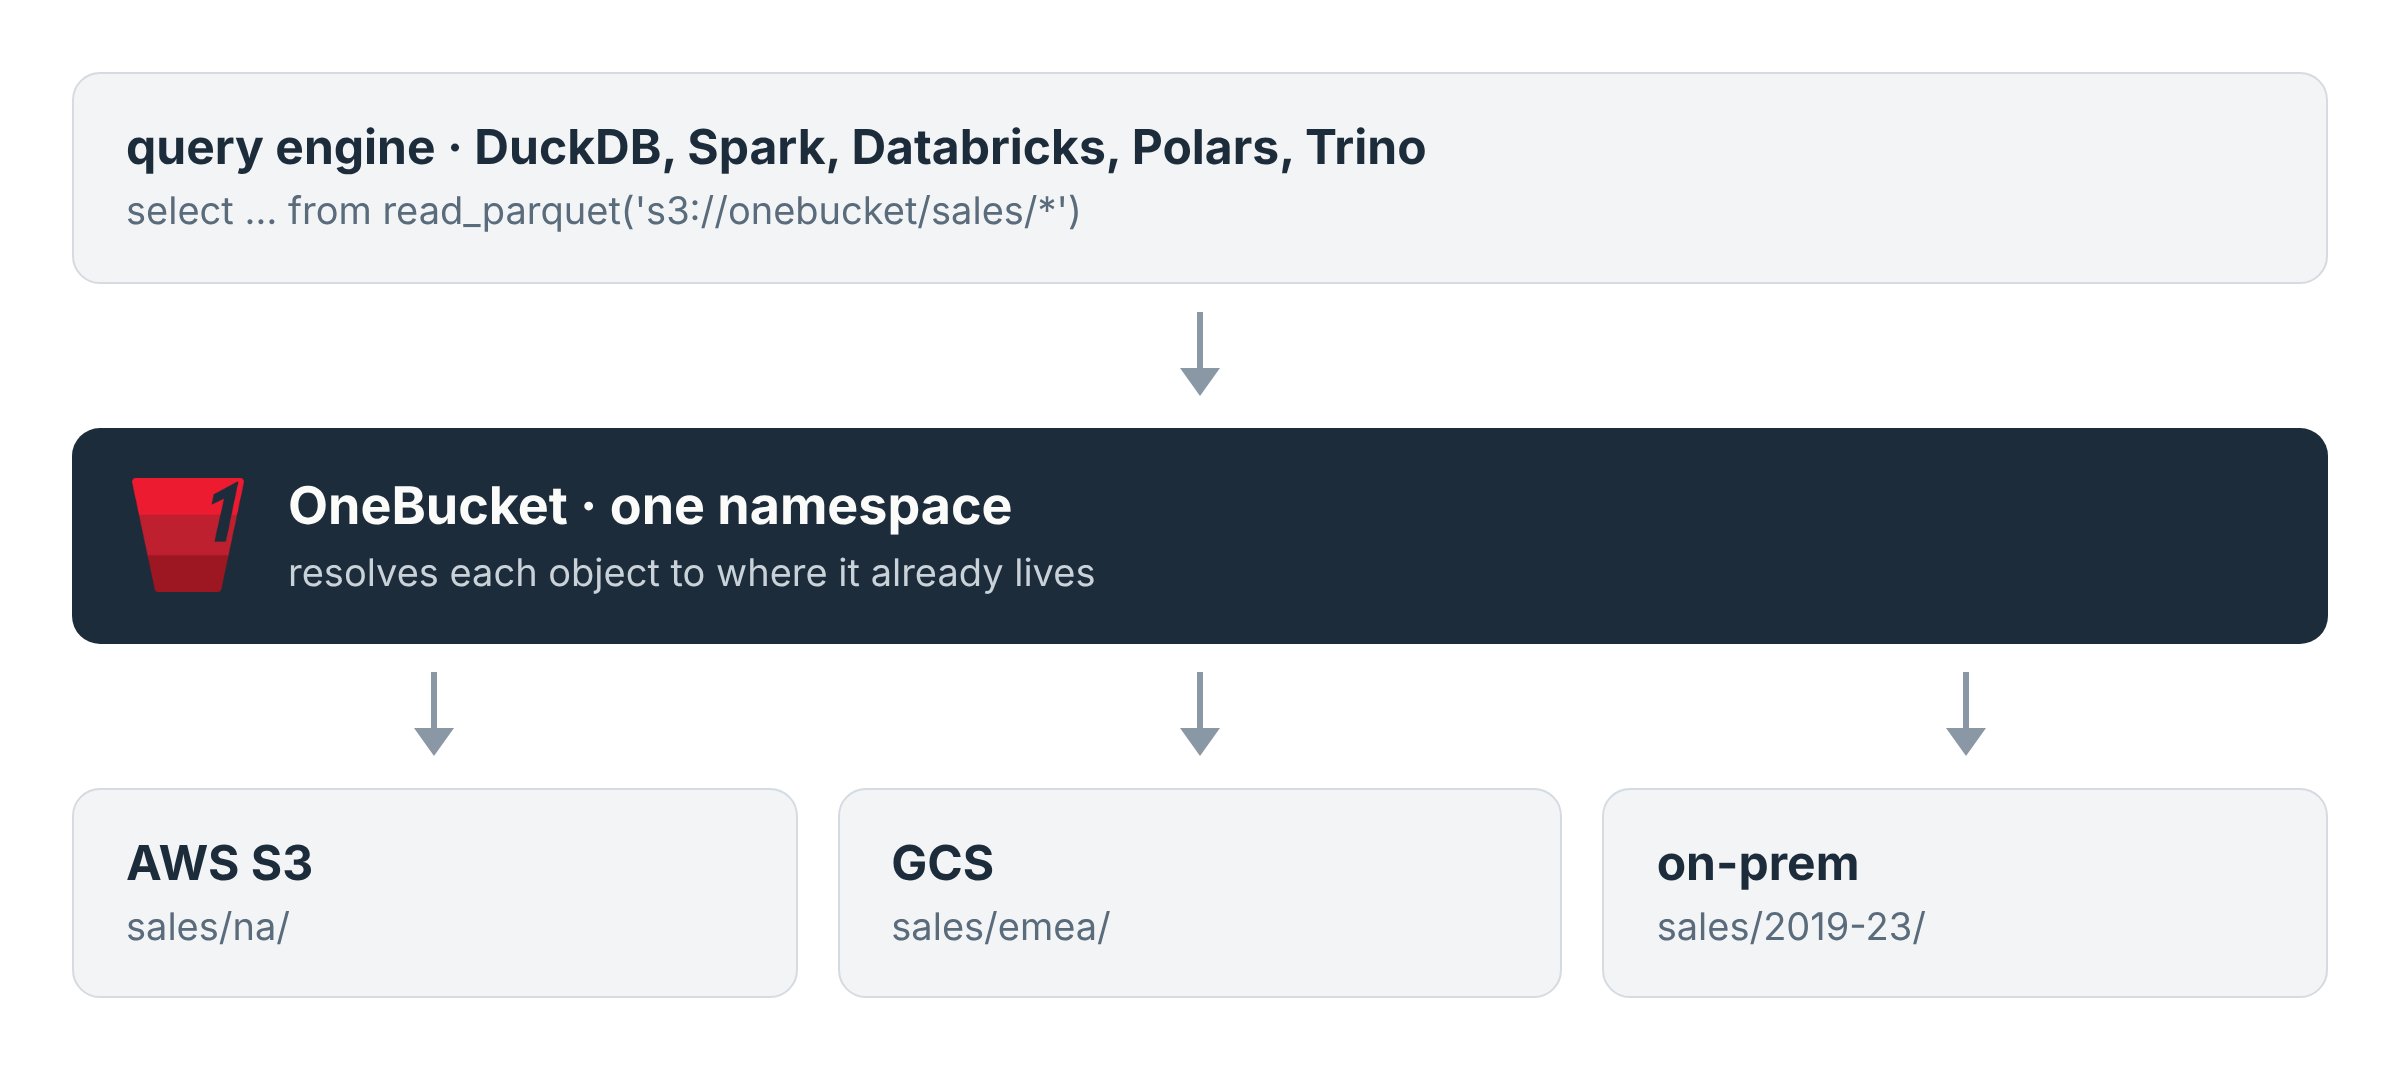
How it works
- The engine runs the query; OneBucket serves the namespace. The engine sees one bucket, so one statement spans Parquet that physically sits in two clouds and an on-prem store.
- Read and write. The S3 endpoint supports full read and write, so results can be written back to the same namespace, and policy decides where they land.
- Unchanged tools. Any engine that reads S3 works as is: point it at the OneBucket endpoint with a OneBucket key.